
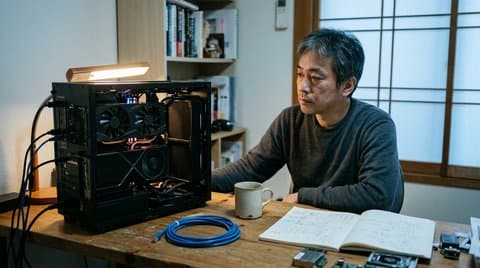
Unplug the Ethernet cable from your workstation for seventy-two hours and watch how much of your engineering stack silently stops functioning. Every autocomplete prompt, every document summarizer, every local code-review script that claims to live on your desk suddenly stalls on a TLS timeout because its brain is actually sitting in a rented warehouse four hundred kilometers away. If you do not own the silicon, you do not own the answers.
Last winter in Akihabara, I stripped three aging cloud-gateway daemons out of my personal research node and replaced them with quantized 8-bit and 4-bit weights running directly across a local PCIe Gen 4 bus. Power draw at idle dropped to eighteen watts. Token generation held steady at sixty-four tokens per second with zero rate-limit headers, zero telemetry egress, and zero monthly invoice waiting to reprice my memory.
Memory Bandwidth Is the Only Truth
Most developers still evaluate local inference by counting floating-point teraflops on marketing sheets. In autoregressive token generation, compute is rarely the bottleneck; memory bus bandwidth is. Every single generated token requires streaming billions of parameter bytes from VRAM or unified RAM into registers. When you quantize weights from 16-bit floating point down to well-calibrated 8-bit integer or 4-bit block-quantized formats, you cut memory-bus traffic by half to three-quarters while preserving over ninety-eight percent of reasoning fidelity on real-world coding and analytical benchmarks.
 Close-up inside an open matte-black workstation chassis showing brushed aluminum finned heatsinks, braided power cables, and PCIe slots
On a desktop workstation with 480 GB/s of local memory bandwidth, a 32-billion-parameter 4-bit model saturates the bus cleanly without thermal throttling and delivers deterministic first-token latency under forty milliseconds—faster than a single round-trip TLS handshake to a congested public API region.
Sovereign Node Execution Path: Local NVMe Weight Load → PCIe Gen 4 DMA Transfer → Quantized Matrix Multiply in Own VRAM → Zero Network Egress → Deterministic Sub-40ms First Token
Every millisecond spent waiting on a remote cloud load balancer is a silent tax on concentration—and an open admission that your tools belong to a landlord.
What the Rentier Cloud Takes Away
The argument for rented intelligence always begins with convenience and ends with dependency. Once an engineering team embeds a proprietary cloud endpoint into its daily workflow, three things happen within eighteen months: latency degrades as noisy neighbors share the cluster, per-token pricing shifts upward once introductory credits expire, and silent weight updates alter model behavior overnight without a single changelog entry.
Infrastructure Dimension | Rented Hyperscaler API Endpoint | Sovereign Bare-Metal Local Node |
|---|---|---|
First-Token Latency | 250–1,400 ms (TLS + queue jitter) | 25–45 ms deterministic on local bus |
Data & Prompt Ownership | Traverses third-party network & tenant logs | Never leaves local RAM or encrypted NVMe |
Model Stability | Silent vendor weight swaps & deprecations | Pinned SHA-256 GGUF/safetensors weights |
Marginal Cost per Million Tokens | Recurring metered rent forever | Fixed electricity (~0.02 kWh per session) |
Offline Survivability | Total failure when Ethernet is pulled | 100% operational in air-gapped silence |
Running your own silicon does not mean pretending a desktop tower can train a frontier model from scratch. It means recognizing that ninety-five percent of daily cognitive work—code audit, local retrieval, structured translation, and synthesis—needs an honest, pinned 8-bit matrix on your own desk rather than a metered pipeline to someone else's datacenter.
Own the Bus, Own the Craft
Keep your weights pinned on local NVMe. Measure your watts at the wall socket. And once a month, pull the RJ45 plug out of the back of the chassis just to prove to yourself that your mind and your machine still work when the rentier cloud goes dark.